What is cron job monitoring?
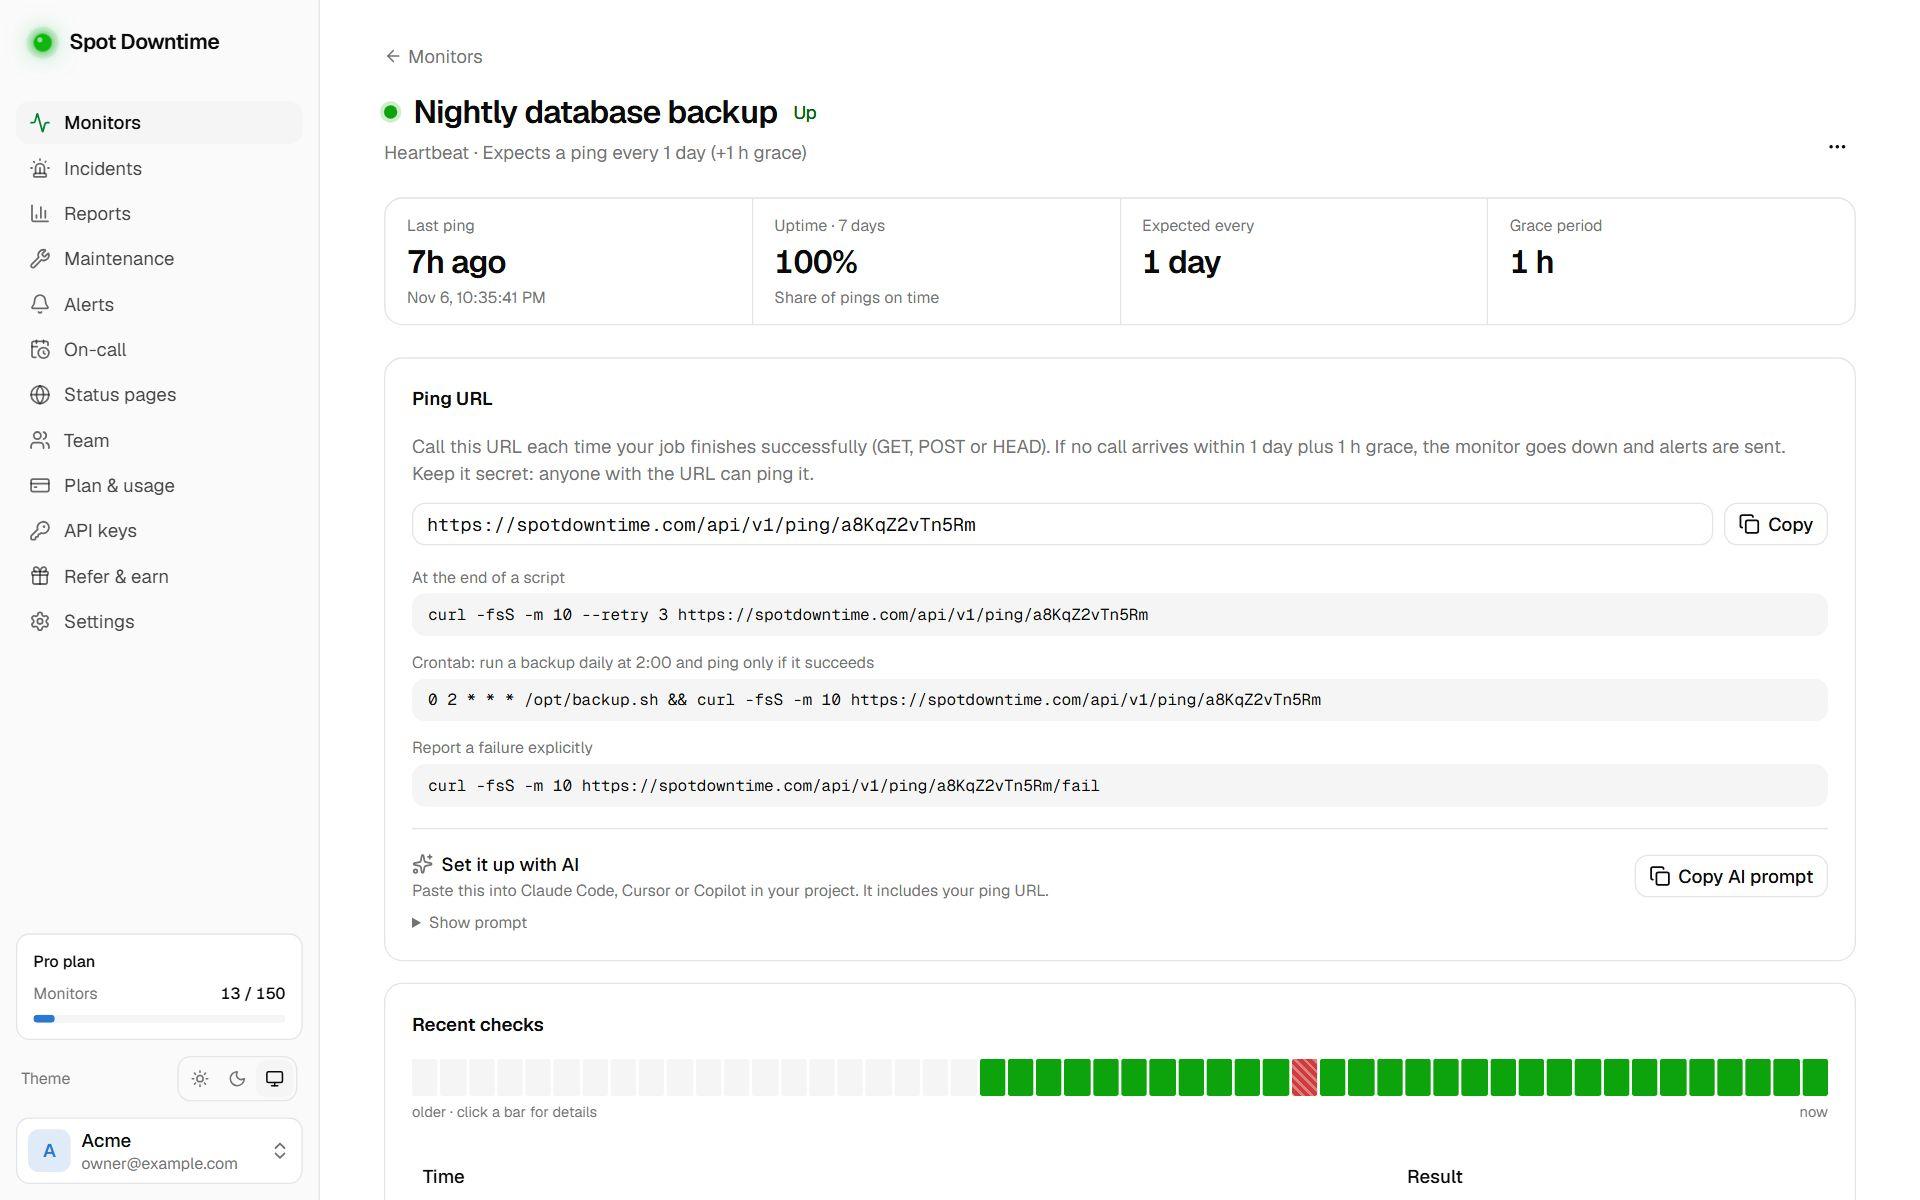
Cron job monitoring, also called heartbeat monitoring, watches for something that should happen on a schedule. Instead of Spot Downtime checking your server, your job checks in: at the end of each run it calls a private ping URL. If the call doesn't arrive within the expected interval plus a grace period, the monitor goes down and your team is alerted.
That catches failures ordinary uptime checks can't see: a crontab entry that was deleted, a server replaced without its scheduled tasks, a job that hangs forever, or a script that has been failing every night for weeks.
Adding a heartbeat to a job
Add one call to the end of the job, for example: /opt/backup.sh && curl -fsS -m 10 followed by your ping URL. The && means the ping only happens when the script succeeds. To report a failure straight away, call the same URL with /fail on the end from your error handling.
Ping with GET, POST or HEAD from anything that can make an HTTP request: curl, wget, PowerShell, Python or Node.js, the last step of a CI pipeline, a Kubernetes CronJob or a scheduled serverless function. There's no agent or library to install.
Choosing the interval and grace period
Set the interval to how often the job runs, from every minute to once a week, and the grace period to how long a run can reasonably take, up to 24 hours. A nightly backup that takes 20 minutes might use 1 day with 30 minutes' grace. You're only alerted once both have passed.
Cron job monitoring is part of the Starter and Pro plans. It sits alongside your website and API monitors in the same workspace, with the same alert channels and incident history.