An alert is only useful if someone acts on it
Uptime monitoring is only as good as the alert that reaches a person. Too few, and an outage runs for an hour before anyone notices; too many, and people mute the channel and miss the real one. Spot Downtime is built to send fewer, better alerts: every failure is re-checked and confirmed from other regions before anyone hears about it, and you get one message when something goes down and one when it recovers, with how long it was down.
Each alert says what failed and why, such as 'HTTP 503 from all 3 regions' or 'Step 3 (Click Checkout): not found', with a link straight to the monitor.
Where alerts go
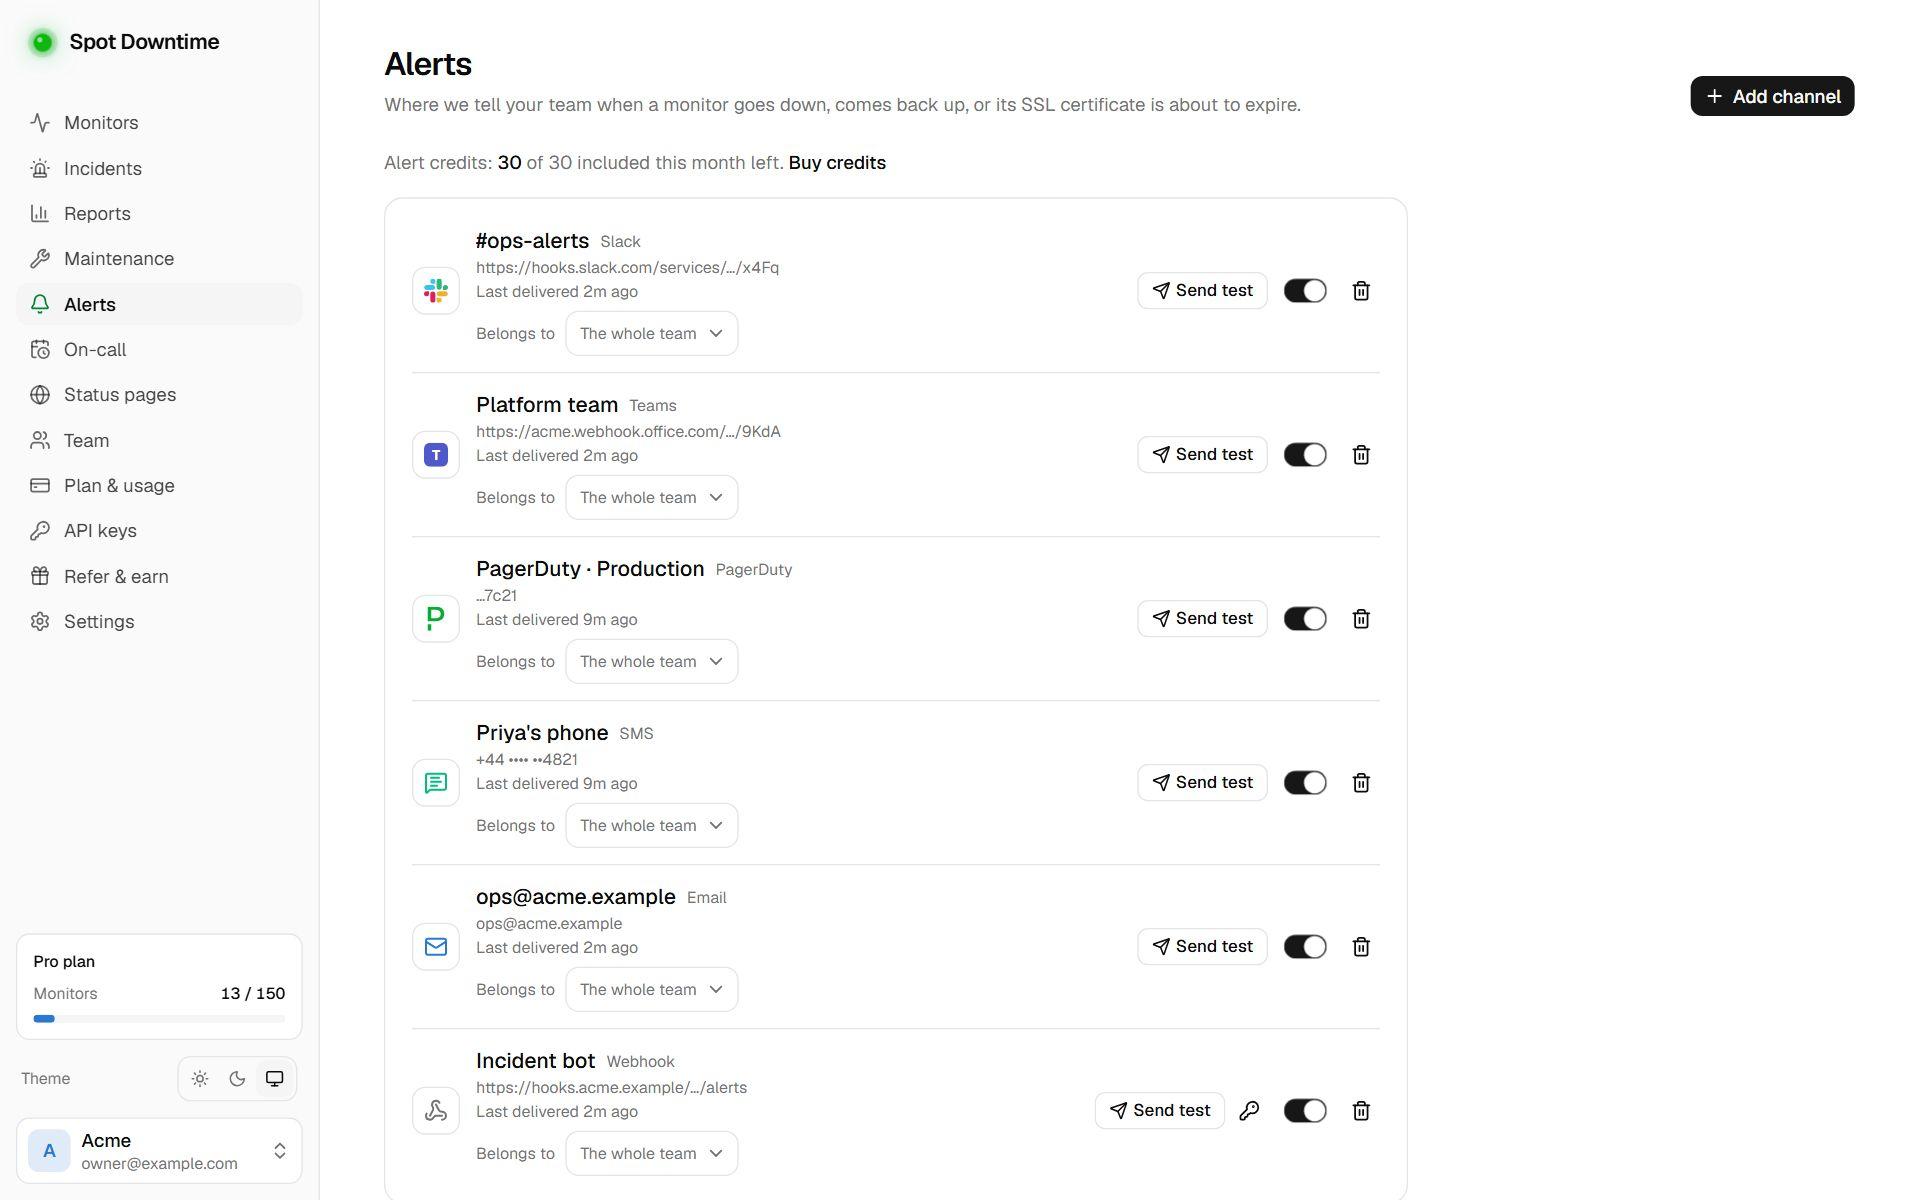
Send them where your team already works: Slack, Microsoft Teams, Discord, Google Chat, Mattermost, Rocket.Chat and Telegram for chat; PagerDuty, Pushover and ntfy for on-call apps; email, SMS, voice calls and WhatsApp for people; and signed JSON webhooks for anything else. Every enabled channel in the workspace gets every alert, so nothing depends on one person remembering to forward it.
Text messages and phone calls are for the outages that can't wait: each plan includes credits every month, and you choose per monitor which ones may text or call. Deliveries that fail are retried, and each channel shows when it last delivered or why it didn't. Send a test from any channel to be sure it works before you need it.
More than up and down
Alerts also warn before things break: SSL certificates and domain registrations get warnings before they expire, and on Starter and Pro, slowness alerts fire when a page's p95 response time stays above your threshold. Servers alert when CPU or memory stays high or a disk fills up, and Docker containers when one crashes or turns unhealthy.
On Pro, escalation policies page people in steps: if nobody acknowledges an incident in time, the next step goes out, and on-call schedules send it to whoever is on call at the time.